 Korean

eISSN : 3022-7011
ISSUER : KIPS
ISSUER : KIPS
After the Korea Information Processing Society (KIPS) Transactions journal was founded in 1994, it was reorganized into the KIPS Transactions: Computer and Communication Systems(2287-5891/2734-049X ) and the KIPS Transactions: Software and Data Engi neering(2287-5905/2734-0503) in 2012. Through the KIPS official meeting on January 8th, 2024, the new KIPS Transaction journal was founded by integrating two KIPS Journals, KIPS Transactions: Computer and Communication Systems and KIPS Transactions: Software and Data Engineering. The new journal aims to realize social value and contribute to the development of South Korea’s science and technology with support from the lottery fund of the Ministry of Strategy and Finance and the science/technology promotion fund of the Ministry of Science and ICT. It is indexed in the Korea Science Academic Database, Korea Citation Index (KCI), and EBSCO.
Publishing with
Highlights More
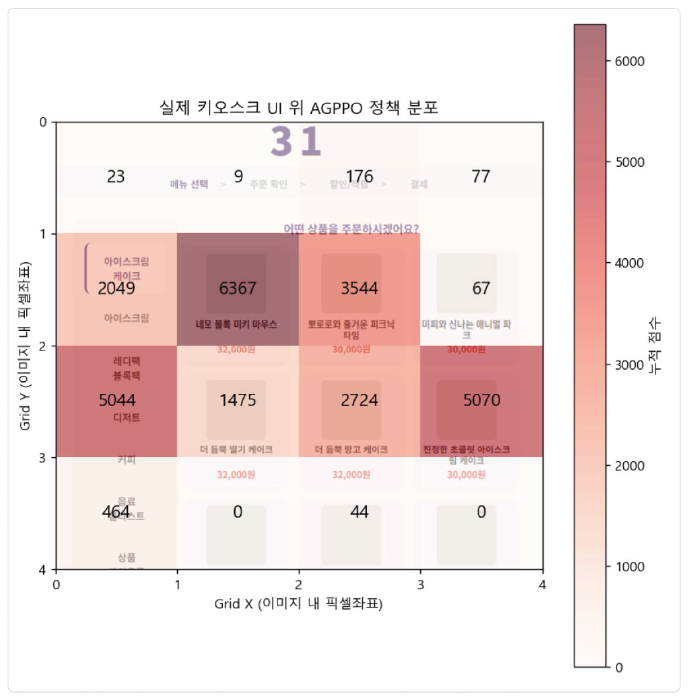
A Study on an AI Evaluation Model for Improving Kiosk Accessibility for the ElderlyChoi Hyeon Seok Kang Hyeon Seo Ji Yu Hwan Lim Chae Eun Dong-Young Yoo |
|
| This study was conducted in response to the surge in demand for barrier-free kiosks following the 2025 amendment to the Anti-Discrimination against Persons with Disabilities Act. Given the limitations of the existing government certification proces... | |
Research on the Use of Multimodal Data for Detecting Emergency Situations Involving Elderly People Living AloneSuyeon Lim Seongbok Baik Yong-Geun Hong |
|
| This study developed a multimodal anomaly detection model to monitor the safety of elderly people living alone in an ageing society, and compared and analysed its performance with that of a single modality model. The data used in the experiment was... | |
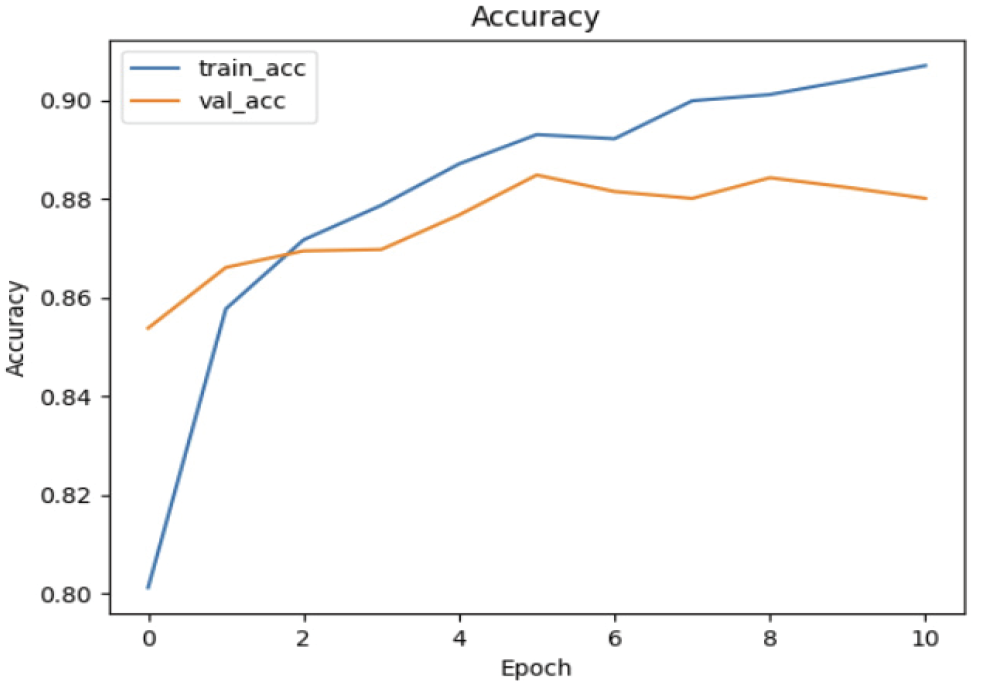
MLSQ: A Multimodal-based System for Learning Material Summarization and Question GenerationGeonwoo Yu Sangyoon Lee Jinyoung Ahn Minha Woo Sugyeong Kim Jungoo Lee Hyeonwoo Choi Yaeran Kim Woonghee Lee |
|
| While the proliferation of digital learning environments has increased the use of diverse multimedia materials, this often leads to passive learning. Existing text-based automatic question generation technologies are insufficient to overcome this li... | |
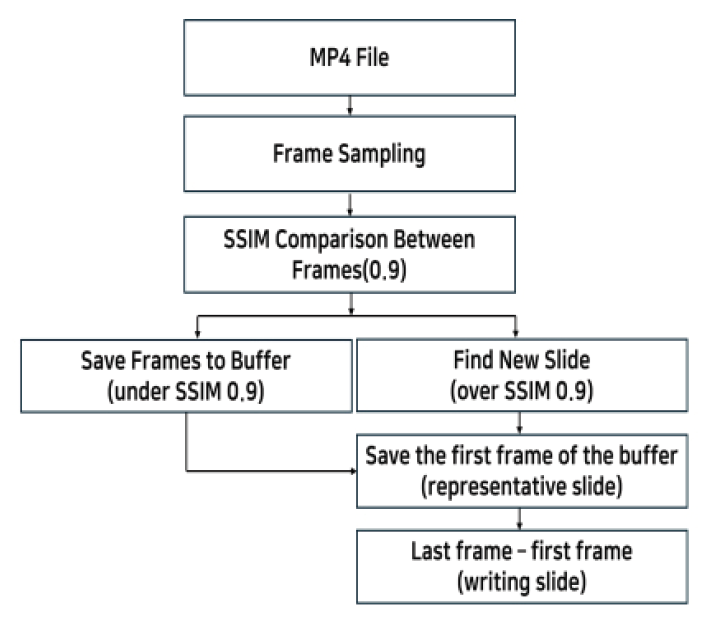
A Study on the Blocking of Malicious Behavior of Generative AI Input Prompts Using Small Language Model ModuleMun Jong In Ryu Dong Hoon Dong-Young Yoo |
|
| Large language models (LLMs) are useful for search, coding, and agentic workflows, but because input prompts directly control their behavior, they are vulnerable to prompt injection (direct and indirect), jailbreaks, format/Unicode evasion, resource... | |
Latest Publication (Vol. 15, No. 8, Aug . 2026)
AI-Based Package Hallucination Detection Framework for Software Supply Chain Security
Hye-Min Hong
Hui-Eun Lim
Ji-Ho Ahn
Yeon-Jin Kim
Il-Gu Lee
 10.3745/TKIPS.2026.15.8.653
information security AI LLM Package & Code Hallucination Detection
The software supply chain's complex dependency structure enables a single vulnerability to escalate into large-scale damage, as clearly
demonstrated by the 2024 XZ Utils incident. In particular, hallucinations generated by Large Language Models (LLMs) have emerged as
a new class of supply chain threats, as they may suggest non-existent packages that lead to the inadvertent installation of malicious
artifacts. To mitigate this risk, this study proposes a Package Hallucination Verification (PHV) framework that integrates PyPI querying
with a cache-based validation mechanism. The proposed approach expands detection coverage to sub-packages through wheel file analysis,
achieves over 90% verification accuracy via One-Shot prompt engineering, and reduces API invocation overhead by 94% through effective
caching. Furthermore, the framework enhances reproducibility by automatically generating a Software Bill of Materials (SBOM) for each
verification process. Experimental results show that PHV has improved performance by 25% in terms of accuracy compared to conventional
studies, demonstrating it as an effective alternative to strengthening supply chain security in the AI-driven development landscape.
The Transactions of the Korea Information Processing Society,
Vol. 15, No. 8, pp. 653-661,
Aug.
2026
10.3745/TKIPS.2026.15.8.653
information security AI LLM Package & Code Hallucination Detection
TD3-Based Dynamic Bandwidth Pricing for MVNO Revenue Maximization in a Network Virtualization Environment
Hyeok-Don Kwon
Kim Sung Wook
10.3745/TKIPS.2026.15.8.662
Network virtualization bandwidth allocation Deep Reinforcement Learning Twin Delayed Deep Deterministic policy gradient algorithm (TD3) game theory Stackelberg Game
With 5G network development, network virtualization has seen increasing use, as it enables operation adapted to diverse requirements
such as video streaming, autonomous driving, and smart factories. In this context, dynamic bandwidth pricing that reflects real-time
demand-supply fluctuations is increasingly important for improving resource efficiency. However, conventional static, rule-based pricing
limits to adapt to changing network states and diverse service needs. To overcome this issue, We propose a reinforcement learning based
dynamic pricing approach that sets prices from real time network information. In this paper, We formulate the interaction between a
mobile virtual network operator (MVNO) and users as a Stackelberg game, where the MVNO posts prices and users purchase bandwidth
to maximize utility. We train the leader’s pricing policy with a Twin Delayed Deep Deterministic Policy Gradient (TD3) agent adapted
to the network environment. To demonstrate the method's superiority, We compare it with a Deep Q-learning (DQN)-based dynamic
pricing model and a fixed price policy. The method acquires the highest average MVNO reward and lower variability in user utility.
The Transactions of the Korea Information Processing Society,
Vol. 15, No. 8, pp. 662-672,
Aug.
2026
10.3745/TKIPS.2026.15.8.662
Network virtualization bandwidth allocation Deep Reinforcement Learning Twin Delayed Deep Deterministic policy gradient algorithm (TD3) game theory Stackelberg Game
An Efficient Ensemble Selection Strategy for Object Detection Using Error Correlation Analysis
Cho Jun Hui
Moon Esther
Moon Nammee
10.3745/TKIPS.2026.15.8.673
Object Detection Ensemble Model Combination Error Correlation Analysis Selection Strategy
This paper proposes a methodology to strategically select optimal ensemble combinations by analyzing inter-model error correlations,
moving beyond simple performance comparisons in object detection. By analyzing the error structure between predictions and Ground
Truth (GT), we define an evaluation index, S, to quantify expected ensemble effects. S prioritizes combinations by integrating miss-detection
complementarity (Gain_{miss}), disagreement (Dis), unique false positive risk (UFP), top-K false positive rate (TFC), and combination stability
(Comp). Experiments with four model types showed that for 2-model combinations, S precisely reproduced actual performance gain
rankings. Notably, the Spearman rank correlation between S and performance gains under WBF reached 0.886 (p < 0.05), confirming
statistical validity. Despite sample size limitations, S also successfully identified optimal 3-model combinations. In conclusion, Score S
serves as a reliable criterion for excluding high-risk pairs and strategically selecting beneficial ensemble partners through post-hoc error
correlation analysis.
The Transactions of the Korea Information Processing Society,
Vol. 15, No. 8, pp. 673-680,
Aug.
2026
10.3745/TKIPS.2026.15.8.673
Object Detection Ensemble Model Combination Error Correlation Analysis Selection Strategy
Pedestrian Risk Area Analysis Using Street View-based Object Detection and Urban Spatial Information
Hae-In Seo
Eun-Chong Lee
Jehyeok Rew
10.3745/TKIPS.2026.15.8.681
Pedestrian Safety Streetview Object Detection Spatial Analysis Large Language Model
Urban spatial information, including road networks and public facilities, is essential for supporting pedestrian safety. However, its
limited update frequency often prevents accurate reflection of dynamic risk factors in real-world walking environments. To address this
limitation, this study proposes a pedestrian safety monitoring approach that integrates street-view–based object detection with urban
spatial information analysis. Areas with a high proportion of elderly residents are selected as case study regions, where pedestrian
vulnerability is particularly critical. Accident-prone locations and road environment characteristics are first defined using GIS-based spatial
data. Pedestrian-obstructing elements, such as illegally parked vehicles, are then detected from street-view images using a YOLO-based
object detection model. The detected objects are spatially integrated with urban datasets to quantitatively estimate pedestrian risk levels
at the regional scale. The resulting risk indicators are visualized as heatmaps, enabling intuitive analysis of spatial hazard distributions.
In addition, the study experimentally investigates the use of large language models (LLMs) and vision-language models (VLMs) to interpret
high-risk areas, providing complementary explanations for complex pedestrian risk factors that are difficult to capture through quantitative
metrics alone. The results demonstrate that the proposed approach effectively complements conventional analyses based on static spatial
information and offers a practical tool for pedestrian safety assessment. This study highlights the potential of data-driven pedestrian
risk monitoring to support evidence-based safety policies and promote age-friendly urban environments.
The Transactions of the Korea Information Processing Society,
Vol. 15, No. 8, pp. 681-695,
Aug.
2026
10.3745/TKIPS.2026.15.8.681
Pedestrian Safety Streetview Object Detection Spatial Analysis Large Language Model
Does Super-Resolution Improve Dermoscopic Image Classification Reliability? A Controlled Study
Kabin Prajapati
Wonsang You
10.3745/TKIPS.2026.15.8.696
Super-resolution Skin Lesion Classification Low-Resolution Imaging Medical Imaging Deep learning
Low-resolution dermoscopic images are common in tele-dermatology, yet it remains unclear whether super-resolution (SR) can recover
diagnostically meaningful information for deep learning–based classification of skin lesions. This study presents a controlled evaluation
of SR as a preprocessing step for multi-class lesion recognition using EfficientNet-B7 trained on ISIC2019. Test images are downsampled
to 64×64 and reconstructed to 256×256 using four representative upscaling methods—SRCNN, SRGAN, ESRT, and bicubic interpolation—
under identical inference conditions. Severe resolution degradation leads to a substantial drop in classification accuracy (91.01% → 49.40%),
while SR provides only limited and method-dependent recovery. Bicubic interpolation yields the best performance (61.80%), ESRT and
SRCNN offer modest improvement (57.20%, 56.60%, respectively). SRGAN performs worst (44.00%) despite producing visually sharper
images. Additional experiments conducted at an intermediate-resolution setting (128×128) show that learning-based SR technique works
more effectively as more information necessary for diagnosis is preserved. Further analysis using confusion matrices and Grad-CAM reveals
that GAN-based SR can introduce hallucinated textures that misguide model attention and increase clinically critical misclassifications.
These findings highlight a disconnect between perceptual image quality and recognition fidelity, cautioning against the uncritical use
of visually driven SR in medical diagnosis and motivating task-aware SR approaches optimized for downstream reliability.
The Transactions of the Korea Information Processing Society,
Vol. 15, No. 8, pp. 696-707,
Aug.
2026
10.3745/TKIPS.2026.15.8.696
Super-resolution Skin Lesion Classification Low-Resolution Imaging Medical Imaging Deep learning
Implicit User Authentication Via Group-Classification Approach to Locomotion Activities Using Smartphone Sensor Data
Min-Ki Kim
10.3745/TKIPS.2026.15.8.708
Smartphone Sensor Data Human Activity Recognition Locomotion Activity Implicit User Authentication
Smartphones store sensitive personal information, such as addresses, financial transactions, and chat content, so making authentication
of smartphone users is increasingly important. This study proposes a system that implicitly authenticates smartphone users based on
locomotion behavior among common activities observed in everyday life. To detect locomotion activities applicable to personal
authentication during daily activities, we propose a group-classification approach that groups activities such as walking, jogging, and
stair climbing into a single class. To identify locomotion activities, we present a convolutional transformer model with relative positional
encoding. Furthermore, a convolutional transformer model with the same architecture is pretrained to identify individuals, which extracts
individual features. A binary Support Vector Machine (SVM) authenticates a smartphone user with the extracted individual features.
Experimental results using two public datasets demonstrate that the proposed transformer model outperforms previous studies in similar
conditions in activity recognition accuracy. They also show that the proposed group-classification method is more effective for personal
authentication than the fine-classification method that subclasses locomotion behaviors.
The Transactions of the Korea Information Processing Society,
Vol. 15, No. 8, pp. 708-716,
Aug.
2026
10.3745/TKIPS.2026.15.8.708
Smartphone Sensor Data Human Activity Recognition Locomotion Activity Implicit User Authentication
Development and Performance Evaluation of a Deep Learning-Based Real-Time Metal Surface Roughness Measurement System Using NVIDIA Jetson Orin NX
Kim Hyun Seok
Yu Yang Jun
Choi Seung Ho
Hong Young Jin
Yoo Cynthia Hye In
10.3745/TKIPS.2026.15.8.717
AI Deep learning quantization Metal surface Surface roughness
This study developed a real-time, non-contact metal surface roughness measurement system for smart factory in-line quality control.
Utilizing an NVIDIA Jetson Orin NX and a CNN model, the system predicts 3D roughness parameters (Sa, Sq) from 2D images. After
training on a dataset of over 5,000 samples and optimizing with TensorRT, it achieved a high precision (R² ≥ 0.95) and an inference
time of 100 ms, satisfying production takt times. Compared to conventional contact-type profilers and cloud-based approaches, the
proposed edge-device system achieves more than 20 times faster measurement speed while maintaining R² ≥ 0.95 precision. This system
offers a practical solution for data-driven intelligent quality management.
The Transactions of the Korea Information Processing Society,
Vol. 15, No. 8, pp. 717-724,
Aug.
2026
10.3745/TKIPS.2026.15.8.717
AI Deep learning quantization Metal surface Surface roughness
SR-KAN: Improving Cross-Domain Robustness in Dermoscopic Super-Resolution with KAN-based Refinement
Sarreha Tasmin Rikta
Wonsang You
10.3745/TKIPS.2026.15.8.725
Super-resolution Kolmogorov-Arnold Network Cross-Domain Robustness Dermoscopy hallucination mitigation
High-resolution dermoscopic imaging is essential for the precise visualization of microstructures, yet device heterogeneity often
introduces domain s hifts that c ompromise automated diagnostic reliability. I n this s tudy, we p ropose S R-K AN, a novel t hree-stage
framework designed for robust and controlled dermoscopic image super-resolution (SR). We redefine SR as a clinical image standardization
task, focusing on two critical challenges: cross-dataset generalization and the mitigation of hallucinated artifacts. The framework integrates
a coarse reconstruction backbone (CNN-based ESRGAN or Transformer-based ESRT) with a specialized Kolmogorov-Arnold Network
(KAN)-based refinement module. Unlike traditional MLPs with fixed activation functions, the KAN-based head leverages learnable edge-wise
nonlinear functions, enabling flexible modeling of complex, high-frequency dermatological textures during refinement. To ensure clinical
applicability, we conducted rigorous cross-dataset evaluations by training on BCN20000 and testing on external datasets (HAM10000 and
ISIC2019).Experimental results demonstrate that KAN-based refinement consistently improves objective and perceptual quality metrics
(PSNR, SSIM, LPIPS, FID, and NIQE), while reducing the risk of hallucinated artifacts under cross-dataset evaluation. By providing a stable
and reliable preprocessing solution, SR-KAN offers a practical framework for trustworthy dermoscopic image enhancement across
heterogeneous acquisition environments. Beyond dermoscopy, the proposed controlled refinement paradigm is model-agnostic and can
be readily extended to other medical and natural image super-resolution scenarios under domain shift.
The Transactions of the Korea Information Processing Society,
Vol. 15, No. 8, pp. 725-734,
Aug.
2026
10.3745/TKIPS.2026.15.8.725
Super-resolution Kolmogorov-Arnold Network Cross-Domain Robustness Dermoscopy hallucination mitigation
Comparative Analysis of Knowledge Graph Integration in Medical QA
Song Yeji
Miao Enwei
Im Dong-Hyuk
Ahn Jinhyun
10.3745/TKIPS.2026.15.8.735
Large-Language Model Knowledge Graph Medical data
This study analyzes the effectiveness of a knowledge graph based Retrieval-Augmented Generation framework as a means to mitigate
hallucination issues and accuracy limitations observed in large language models in medical question answering environments. Experiments
were conducted using GPT-2 and LLaMA-2 models on the MedMCQA dataset for multiple-choice question answering and the PubMedQA
dataset for descriptive question answering, incorporating PrimeKG and a PubMedQA-based knowledge graph. Experimental results show
that models integrated with knowledge graphs achieved measurable performance improvements compared to their baseline counterparts.
On the MedMCQA dataset, the accuracy of the GPT-2 model improved from 0.2596 to 0.2737, while on the PubMedQA dataset, the accuracy
of the LLaMA-2 model increased from 0.3838 to 0.43. In addition, sentence-level semantic similarity of descriptive answers improved
to 0.7041 for GPT-2 and 0.8116 for LLaMA-2, indicating that knowledge graph–based external knowledge contributes to enhancing
generation quality. These findings suggest that the effectiveness of external knowledge utilization may vary depending on the question
answering format and the level of domain expertise required. Furthermore, the results imply that knowledge graph–based approaches
can be effective in improving the reliability and accuracy of LLM responses in medical environments where specialized knowledge is
essential.
The Transactions of the Korea Information Processing Society,
Vol. 15, No. 8, pp. 735-743,
Aug.
2026
10.3745/TKIPS.2026.15.8.735
Large-Language Model Knowledge Graph Medical data
A Comparative Study of Retrieval Methods for Domain-Specific RAG in IT Audit
Oh Haeng Un
You Jin-Ho
10.3745/TKIPS.2026.15.8.744
RAG Sparse Retrieval Dense Retrieval Hybrid Retrieval
In domain-specific RAG, retrieval quality is critical to generation quality, yet the relative effectiveness of sparse, dense, and hybrid
retrieval remains insufficiently validated in professional domains with standardized terminology such as IT audit. This study compares
the performance of sparse, dense, and hybrid retrieval methods in the retrieval stage of a RAG pipeline using a domain-specific QA
dataset constructed manually by professional IT auditors affiliated with CAS Co., Ltd., based on nine practical audit guideline documents.
A total of 16,967 samples were used after applying an input-length constraint, and 3,370 samples (20% of the dataset) served as the
query set. Solr 10.0.0 was used as the search engine and BGE-M3 as the embedding model. Six comparative experiments encompassed
sparse retrieval with and without lexical resources, dense retrieval with HNSW parameter tuning, and hybrid retrieval with two-stage
alpha (α) search. The results show that BM25-based sparse retrieval with lexical resources achieved an MRR of 0.3037, outperforming
the best dense retrieval setting (MRR 0.2475) by 22.7%. Hybrid retrieval achieved the highest MRR of 0.3120, but its improvement over
sparse retrieval was limited to 2.73%. These findings suggest that in domains with high lexical alignment and standardized terminology,
sparse retrieval may be more effective than dense retrieval, highlighting the importance of domain-aware retrieval design and empirical
validation in RAG systems.
The Transactions of the Korea Information Processing Society,
Vol. 15, No. 8, pp. 744-753,
Aug.
2026
10.3745/TKIPS.2026.15.8.744
RAG Sparse Retrieval Dense Retrieval Hybrid Retrieval
Analysis of Age-Related Differences in Physiological and Postural Control Characteristics in Women Based on Multimodal Physiological Signals
SeungJun Oh
Dong-Keun Kim
10.3745/TKIPS.2026.15.8.754
Multimodal Physiological Signals Aging ECG EMG CoP Postural Control Data-Driven Analysis
This study aimed to investigate age-related differences in physiological characteristics and postural control in women using multimodal
physiological signals, including Electrocardiography (ECG), Electromyography (EMG), and Center of Pressure (COP). A total of 87 participants
were included, comprising 30 women in their 20s and 57 healthy elderly women aged 65 years and older. P hysiological s ignals were
collected during quiet standing, semi-tandem stance, and the Five Times Sit-to-Stand (FTSS) test.
Time-domain heart rate variability (HRV) features were extracted from ECG signals, while frequency-domain features were derived
from EMG signals, and COP-based parameters were computed to assess postural control. Statistical analyses and data-driven classification
models were applied to evaluate group differences and discriminative performance.
The results showed that elderly women exhibited reduced HRV, lower EMG frequency characteristics, and decreased postural stability
compared to younger women. Among the individual modalities, ECG demonstrated the highest classification performance, whereas EMG
showed relatively lower performance. COP-based classification performance varied depending on postural conditions, with the
semi-tandem stance yielding the highest performance. These findings suggest that multimodal physiological signals provide an effective
framework for quantitatively assessing age-related physiological changes and postural control.
The Transactions of the Korea Information Processing Society,
Vol. 15, No. 8, pp. 754-761,
Aug.
2026
10.3745/TKIPS.2026.15.8.754
Multimodal Physiological Signals Aging ECG EMG CoP Postural Control Data-Driven Analysis
Latent Space Alignment-Based Translation of Mental Imagery EEG into Perception-like EEG Representations
Mental imagery electroencephalography (EEG) is inherently challenging to model because imagery-related neural activity is internally
generated, weakly time-locked, and exhibits high variability compared to visually evoked perception EEG. This variance may introduce
residual temporal misalignment between mental imagery and perception EEG. Consequently, conventional regression-based models that
assume a strict temporal correspondence and optimize solely for pointwise reconstruction errors encounter strict limitations in translation
performance and interpretability. To address these challenges, we propose a jitter-aware generative framework for translating mental
imagery EEG into perception-like EEG representations by explicitly modeling temporal alignment within a latent space while constraining
signal generation within a learned perception manifold. A conditional variational autoencoder (CVAE) is first trained on perception EEG
to construct a structured latent space that effectively captures the physiological spatiotemporal and spectral structures of perceptual brain
activity. Mental imagery EEG is then mapped into this regularized latent space via a hybrid encoder that integrates temporal, spectral,
and spatial information, combined with a lag-prediction module that estimates trial-by-trial latent alignment parameters before decoding.
Using a public natural-scene mental imagery/perception EEG dataset comprising 49 participants, we evaluated the framework under a
subject-independent protocol over multiple random seeds (N=5). The proposed framework achieved higher sensor-level spatial consistency
than the direct U-Net regression baseline, improving the topographic correlation from 0.811 ± 0.014 to 0.848 ± 0.010. In contrast, the
direct U-Net baseline achieved lower pointwise reconstruction error and higher structural similarity (SSIM), suggesting a trade-off between
pointwise numerical accuracy and sensor-level spatial consistency. Furthermore, the learned temporal shifts exhibited a narrow and
consistent distribution, supporting their interpretation as model-based alignment parameters within the latent representation space rather
than direct neurophysiological latency estimates. These findings suggest that latent-space alignment within a learned perception manifold
may provide a useful alternative to conventional regression-based EEG translation, particularly when preserving sensor-level spatial
organization is important.
The Transactions of the Korea Information Processing Society,
Vol. 15, No. 8, pp. 762-775,
Aug.
2026
10.3745/TKIPS.2026.15.8.762
Electroencephalography Mental Imagery Latent Space Alignment Perception-Like EEG Representation Generative Neural Signal Translation Perception Manifold Brain–Computer Interface
Indexing
All publications of TKIPS is indexed in DOI, EBSCO, Google Scholar, Crossref, and CrossCheck.


TKIPS is also selected as the Journal for Accreditation by NRF (National Research Foundation of Korea).